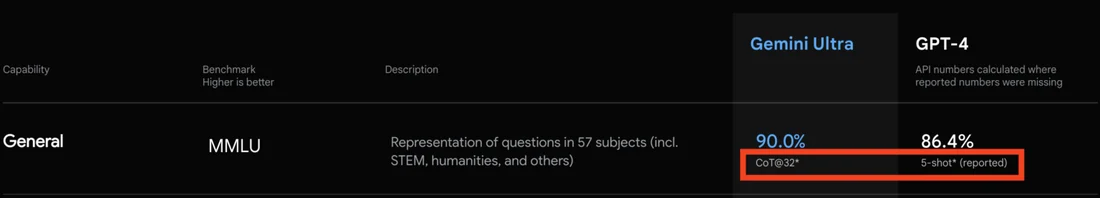
A single test spanning 57 subjects
The Measuring Massive Multitask Language Understanding paper, submitted to arXiv on 7 September 2020, introduced a multiple-choice benchmark covering 57 subjects grouped into humanities, social sciences, STEM and a miscellaneous other category. Questions range from elementary mathematics to US history, law and professional medicine, each with four answer options drawn from real exam and quiz material. The paper reports that the largest GPT-3 model of the time improved on random-chance accuracy by roughly twenty percentage points on average, while performance on subjects such as morality and law stayed close to chance. That gap between an average score and subject-level detail is the first thing a reader of any MMLU number should ask about: an aggregate percentage can hide subjects where a model is barely better than guessing.
How the score is produced
MMLU is scored as plain accuracy on four-way multiple choice, and the original paper evaluated models in a few-shot setting rather than after fine-tuning on the test subjects. The accompanying evaluation repository distributes a small development set for building prompts, a validation set, and the held-out test questions, and it has been used by many labs as the basis for reported numbers even where the exact prompt template differs. That variation matters: a later benchmark built on the same idea, MMLU-Pro, found that answer format and the presence or absence of step-by-step reasoning could shift a model's original MMLU score by roughly four to five percentage points, wide enough to change a leaderboard ranking on its own.
Saturation, noise and what a score no longer tells you
By 2024, frontier models were scoring high enough on MMLU that the test stopped separating them well. The MMLU-Pro paper, submitted 3 June 2024, describes the original benchmark as having begun to plateau and responds by expanding each question to ten answer choices, adding harder reasoning-dependent items, and removing questions it judged trivial or noisy. That clean-up pass is itself evidence that some fraction of the original 57-subject set was ambiguous or mis-keyed. Separately, because MMLU questions are drawn from publicly available exam and quiz sources, the same text can appear inside training corpora assembled after 2020, a distinct problem from difficulty that neither paper measures directly.
Questions to carry into your own evaluation
- Is the reported number an overall average, or does it show which of the 57 subjects were weak?
- What prompt format and shot count produced this score, and would a different template move it by more than the gap between the two models being compared?
- Is the model recent enough, relative to its training cutoff, that these exact MMLU questions could plausibly have been seen during training?
MMLU did something genuinely useful in 2020: it replaced a handful of narrow tasks with a broad, checkable multiple-choice sweep. It was never designed to survive four years of frontier-model progress unadjusted, and its successors exist because the original test's headline number eventually said less than it once did.
Sources & reading trail
Establishes the 57-subject multiple-choice benchmark, its few-shot evaluation, and the average accuracy gain reported for GPT-3.
Source published: 7 September 2020 · Retrieved: 16 September 2026
Documents the benchmark's subject categories, four-way multiple-choice format and dev/validation/test split, as retrieved 16 September 2026.
Source published: Not established · Retrieved: 16 September 2026
Reports that MMLU had plateaued, that prompt formatting shifted scores several points, and that MMLU-Pro removed noisy or trivial questions.
Source published: 3 June 2024 · Retrieved: 16 September 2026
Papers and official documents establish the record; the reading and the questions are Model Field Guide editorial analysis. This retrospective draft does not imply the site published on the event date.